
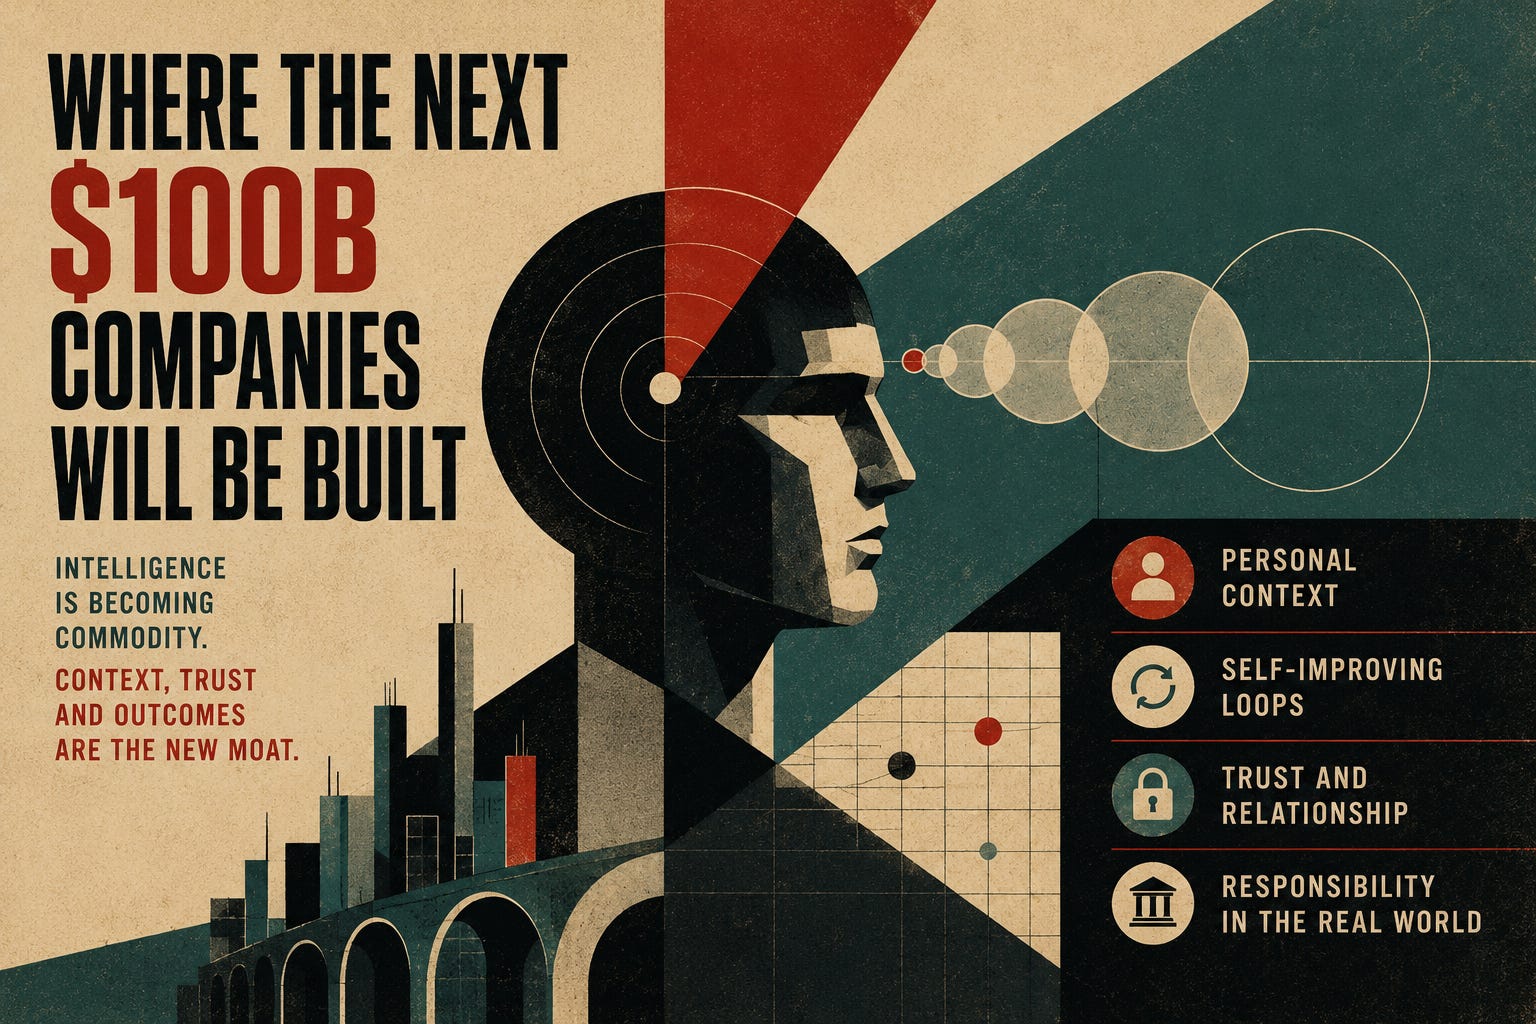
There is a question hanging over almost every AI startup right now:
What happens if models become ten times better
and ten times cheaper?
For some companies, the answer is wonderful. For others, it is: “Well, our entire product just became a prompt.”
That is the starting point of an interesting essay shared by Stepan from cyber•Fund, Where the Next $100B Companies Will Be Built.
Its central argument is simple:
AI is commoditizing intelligence, so companies need to build their moats somewhere intelligence cannot be commoditized.
I think this is broadly right, and more importantly, it gives us a useful framework for thinking about what an AI-native company actually is. Because adding Claude to SaaS is not one.
The Old Software Factory
The great software businesses of the last generation were essentially factories for producing identical experiences.
Google built one search engine and distributed it to billions of people. Slack built one collaboration product. Notion built one workspace. Salesforce built one CRM architecture and configured it around thousands of organizations. This model made economic sense because software was expensive to create and almost free to reproduce.
You might spend five years and hundreds of millions building the product. But customer number 10,000,001 costs almost nothing to serve compared with customer number 10,000,000.
So the winning strategy became:
Build once. Distribute infinitely.
AI changes an important variable in that equation. The cost of producing intelligence is collapsing. And once intelligence becomes cheap, identical experiences become less necessary.
One Product for a Million People Becomes a Million Products
This is probably the most important idea in the essay. Traditional software needed standardization. AI makes personalization economically viable.
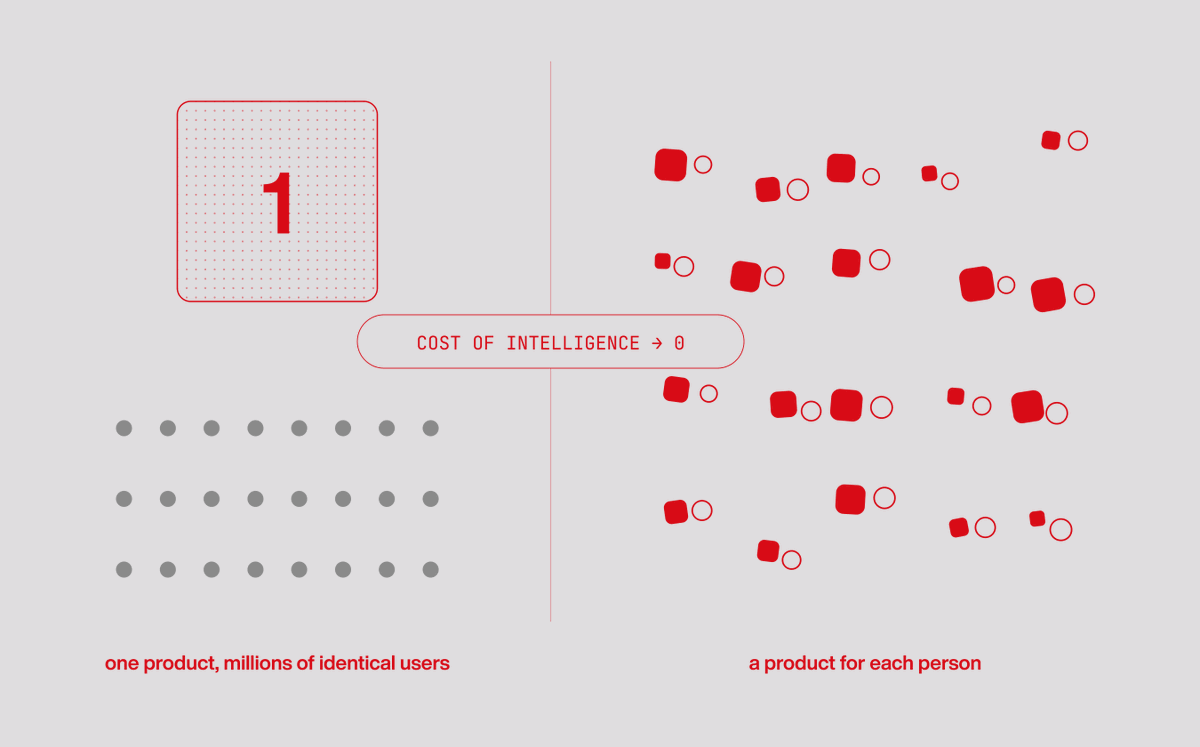
Instead of: one product → millions of users
we can increasingly build:
one user → one continuously adapting product
That sounds like a small distinction. It isn’t. Consider education.
Traditional educational software gives ten thousand students roughly the same curriculum with some personalization around the edges.
An AI-native educational system can theoretically construct a different sequence for every student based on what they understand, where they struggle, how quickly they learn, what motivates them, and what they did yesterday.
The software stops being something you use. It becomes something that reorganizes itself around you. That is a fundamentally different product architecture.
The Verification Gradient
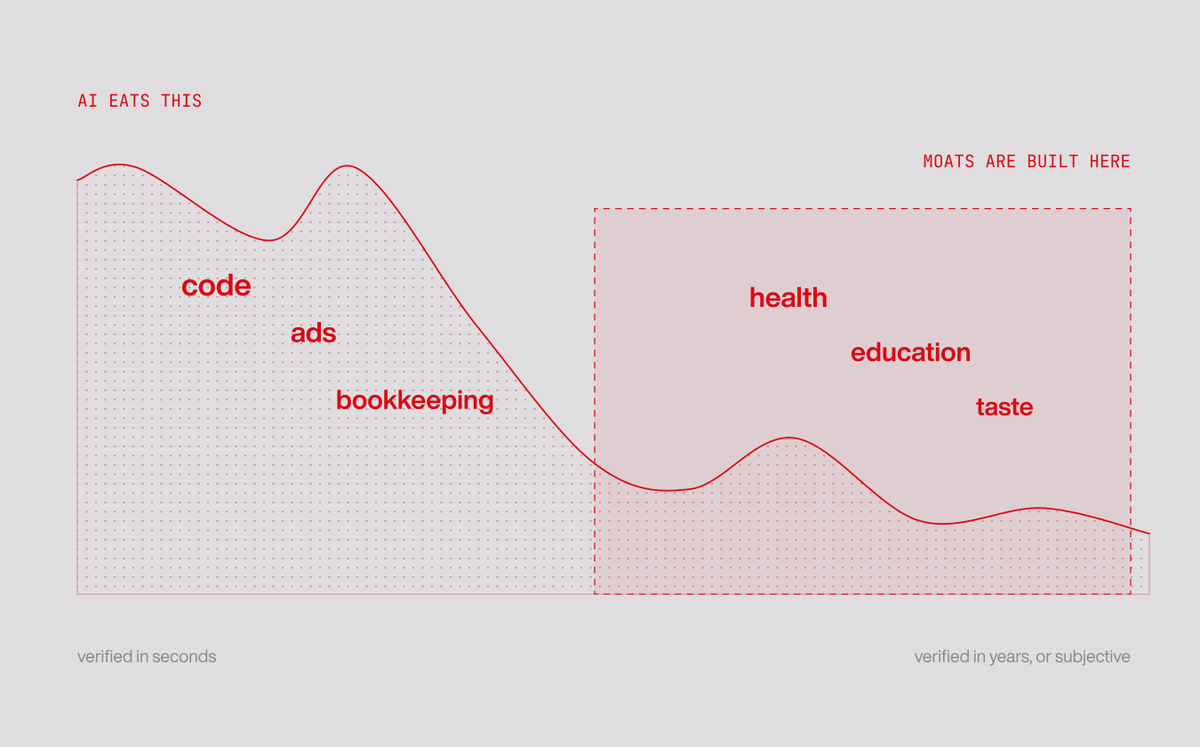
The essay introduces another useful distinction: how quickly an outcome can be verified.
Some work has extremely fast feedback. Code either passes the tests or doesn’t. An advertisement converts or doesn’t. A ledger balances or doesn’t. These domains are particularly vulnerable to AI commoditization because models can generate an answer, observe the result, correct themselves and iterate rapidly.
Software engineering sits very close to this end of the spectrum. Which is one reason coding capability is improving at such ridiculous speed.
Other domains have slow or subjective verification: Health. Education. Taste. Relationships. Long-term financial decisions.
You don’t know whether a medical intervention improved someone’s life five seconds after generating it. You may not know for months. Sometimes years. And sometimes there isn’t a clean objective answer at all.
The essay argues that this is where new defensibility begins to appear. I would phrase it slightly differently: AI eats fastest where reality provides cheap feedback.
Where feedback is slow, expensive, regulated, physical, subjective or deeply contextual, businesses still have room to build durable advantage.
The Most Interesting Example Is Healthcare
Imagine an AI healthcare company that doesn’t sell you another health dashboard.
Instead, it knows: your sleep, blood tests, training, diet, medication history, wearable data, previous interventions, goals, and how your body responded to all of them. It doesn’t merely recommend that you visit a doctor. It manages the process.
Orders the appropriate tests. Tracks the results. Changes protocols. Escalates to a human physician when necessary. Suddenly you’re not buying software. You’re buying an outcome.
This is important because wealthy people have effectively purchased this kind of personalization for decades. They simply did it with humans. Concierge doctors. Personal trainers. Nutritionists. Assistants. Analysts.
AI potentially turns something that previously required hundreds of thousands of dollars of human attention into a service costing hundreds or thousands. That is the kind of market expansion AI makes possible.
Personalization as a Network Effect With n=1
This is perhaps my favorite line in the essay. A competitor can clone your interface. Increasingly, it can clone your entire application.
Give a competent coding agent screenshots, documentation and enough time, and the visible software may no longer be much of a moat. But it cannot easily clone three years of interaction between you and the product: Your preferences. History. Corrections. Measurements. Failures. Successful interventions. Context.
The product becomes better specifically because you have been using it. Every interaction increases its value to you and increases the cost of leaving. Traditional network effects become stronger as the number of users grows. This version compounds even with one.
Hence: network effect, n=1.
I think we’ll hear much more about this idea.
But There Is Another Loop
Personal context creates one moat. Aggregated experience creates another.
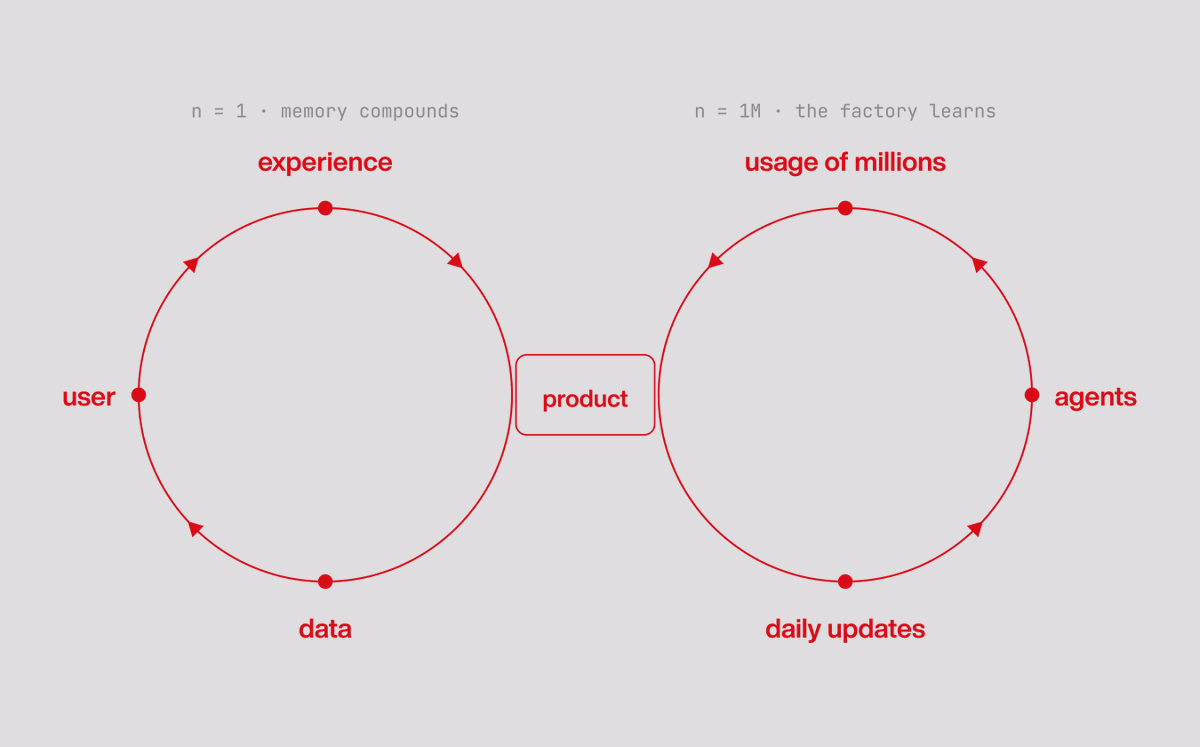
Imagine a product serving one million users. Traditionally, usage data flows into analytics. Product managers inspect dashboards. Researchers run experiments. Engineers eventually ship something. AI-native systems can compress that loop dramatically. Observed behavior can feed directly into agents that modify workflows, personalization strategies, prompts, evaluations and potentially the product itself.
The loop becomes:
usage → learning → agents → product improvement → more usage
The company with more users doesn’t merely have more data. It potentially has a product that learns faster. This is where AI-native scale starts looking interesting again.
The standardized product disappears, but scale remains valuable because millions of individualized experiences collectively improve the system generating them.
The Sandwich Company
The essay then introduces a framework I think is particularly useful for founders. Future AI companies may increasingly consist of three layers.
At the top: Relationship - Context, memory, identity and trust.
In the middle: Intelligence - Models and agents.
At the bottom: Atoms - Doctors, laboratories, licenses, logistics, factories, insurance, physical infrastructure and regulatory responsibility.
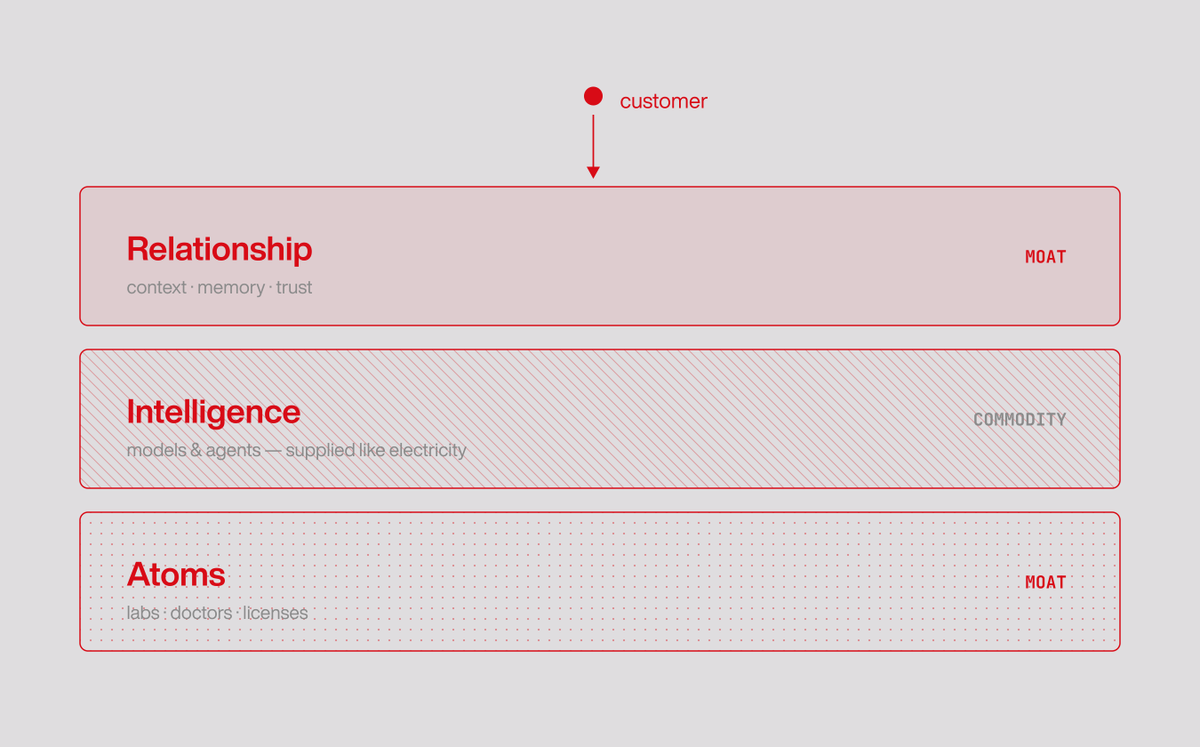
And here’s the twist: The middle layer may become the least defensible one.
Everyone gets access to increasingly similar frontier intelligence. Models become infrastructure. Something closer to electricity.
The durable company therefore owns what sits above and below the model. That is a significant reversal from the current startup obsession with proprietary AI capability.
Responsibility May Be a Moat
The bottom layer contains another scarcity that I think deserves more attention than it receives: liability.
A model can recommend something. Someone still has to be responsible when it goes wrong. This becomes particularly important in healthcare, finance, law, infrastructure and other regulated industries: Licenses matter. Insurance matters. Contracts matter. Physical operations matter. Someone has to sign their name.
Ironically, the future’s most defensible AI companies may therefore be much less purely digital than the software giants they replace.
The AI itself becomes commodity infrastructure. The business becomes the trusted organization capable of turning intelligence into real-world outcomes.
The Best Test for an AI Startup
The essay proposes a wonderfully brutal question:
If models become ten times smarter tomorrow,
does your company grow or die?
Every AI founder should probably put that above their desk. If your advantage is that you wrote better prompts… bad news.
If it’s your wrapper… also bad news.
If it’s simply that you integrated the newest model three months before everyone else… enjoy the three months.
But if better models make your accumulated context more valuable, your agents more capable, your customer relationships deeper and your physical operations more efficient? Then every frontier-model release strengthens you. That’s where you want to be.
Where I Agree, and Where I’m Less Certain
I strongly agree with the essay’s central direction. Software itself is becoming less scarce. Personal context, trust, distribution, responsibility and real-world execution aren’t. But I wouldn’t declare traditional software moats dead quite yet.
Enterprise systems of record remain extraordinarily sticky. Data models matter. Integrations matter. Security architecture matters. Workflow ownership matters. Regulatory certification matters. And switching costs remain very real.
AI reduces the cost of recreating software. It does not automatically reduce the cost of replacing an embedded institution. That’s an important distinction.
The death of code as a moat doesn’t necessarily imply the death of software companies. It means successful software companies need their moat to migrate elsewhere.
The Bigger Idea: Scarcity Moves
This is ultimately what I took from the essay. Technology doesn’t eliminate economic value. It moves scarcity.
When computation became cheap, value moved toward software. When software distribution became cheap, value moved toward networks, brands and data. Now intelligence itself is becoming cheaper. So value moves again.
Toward context. Trust. Taste. Responsibility. Physical infrastructure. Unique relationships. Accumulated experience. And the ability to deliver complete outcomes rather than another collection of buttons.
The next $100B AI company may still contain an enormous amount of software.
You simply won’t buy it because of the software. You’ll buy it because it knows you, improves with you, takes responsibility, interacts with the physical world and solves the entire problem.
The software will just be the plumbing. And plumbing, historically, is rarely where the moat lives.
"Technology doesn't eliminate value, it moves scarcity" is the line I'm keeping. Where I'd push a layer further: the usage-to-learning-to-agents loop you describe doesn't stay inside one company. The n=1 moat is real, but the faster-compounding one is the network, partners, talent, even rivals, teaching a system what to build next quicker than a closed competitor can learn it. Ownership of the stack starts to look downstream of learning rate. And responsibility as a moat may be the sharpest point here: someone still has to sign their name, and that never got cheap.